AI, Full-stack
KODEKS: a retrieval-augmented legal assistant for Bosnian law
A legal assistant for police officers in Bosnia and Herzegovina, built with Next.js, Supabase pgvector, OpenAI embeddings and Claude, that answers only from the law and shows where every answer comes from.
- Client
- ANODA product
- Year
- 2026
- Role
- Product, architecture and full implementation
- Status
- In development, built for police officers in Bosnia and Herzegovina. No public demo.
- Type
- RAG system (retrieval-augmented generation)
 Illustration
At a glance
| Domain | Legal, law enforcement |
|---|---|
| Users | Police officers in Bosnia and Herzegovina |
| Corpus | National legislation in Bosnian |
| Approach | Retrieval-augmented generation with source citations |
| Embeddings | OpenAI text-embedding-3-small, multilingual |
| Vector store | Supabase PostgreSQL + pgvector |
| LLM | Anthropic Claude API |
| App | Next.js |
| Status | In development, no public demo |
The problem
Police officers in Bosnia and Herzegovina need fast, reliable answers from laws and regulations that are long, fragmented and written in Bosnian. In the field, there is no time to search through several laws to find the one article that applies.
General chatbots are not an option: they either do not know local law or invent it, and a confident wrong answer about the law is worse than no answer at all. Searching PDF files is accurate but slow, and it only works if you already know the exact words the law uses.
Why not a general chatbot?
| General chatbot | Search in PDF files | KODEKS | |
|---|---|---|---|
| Knows Bosnian law | Partly | Yes | Yes |
| Answers in plain language | Yes | No | Yes |
| Shows the source | No | Yes | Yes |
| Admits when it does not know | No | Partly | Yes |
| Works with BHS spelling variants | Partly | No | Yes |
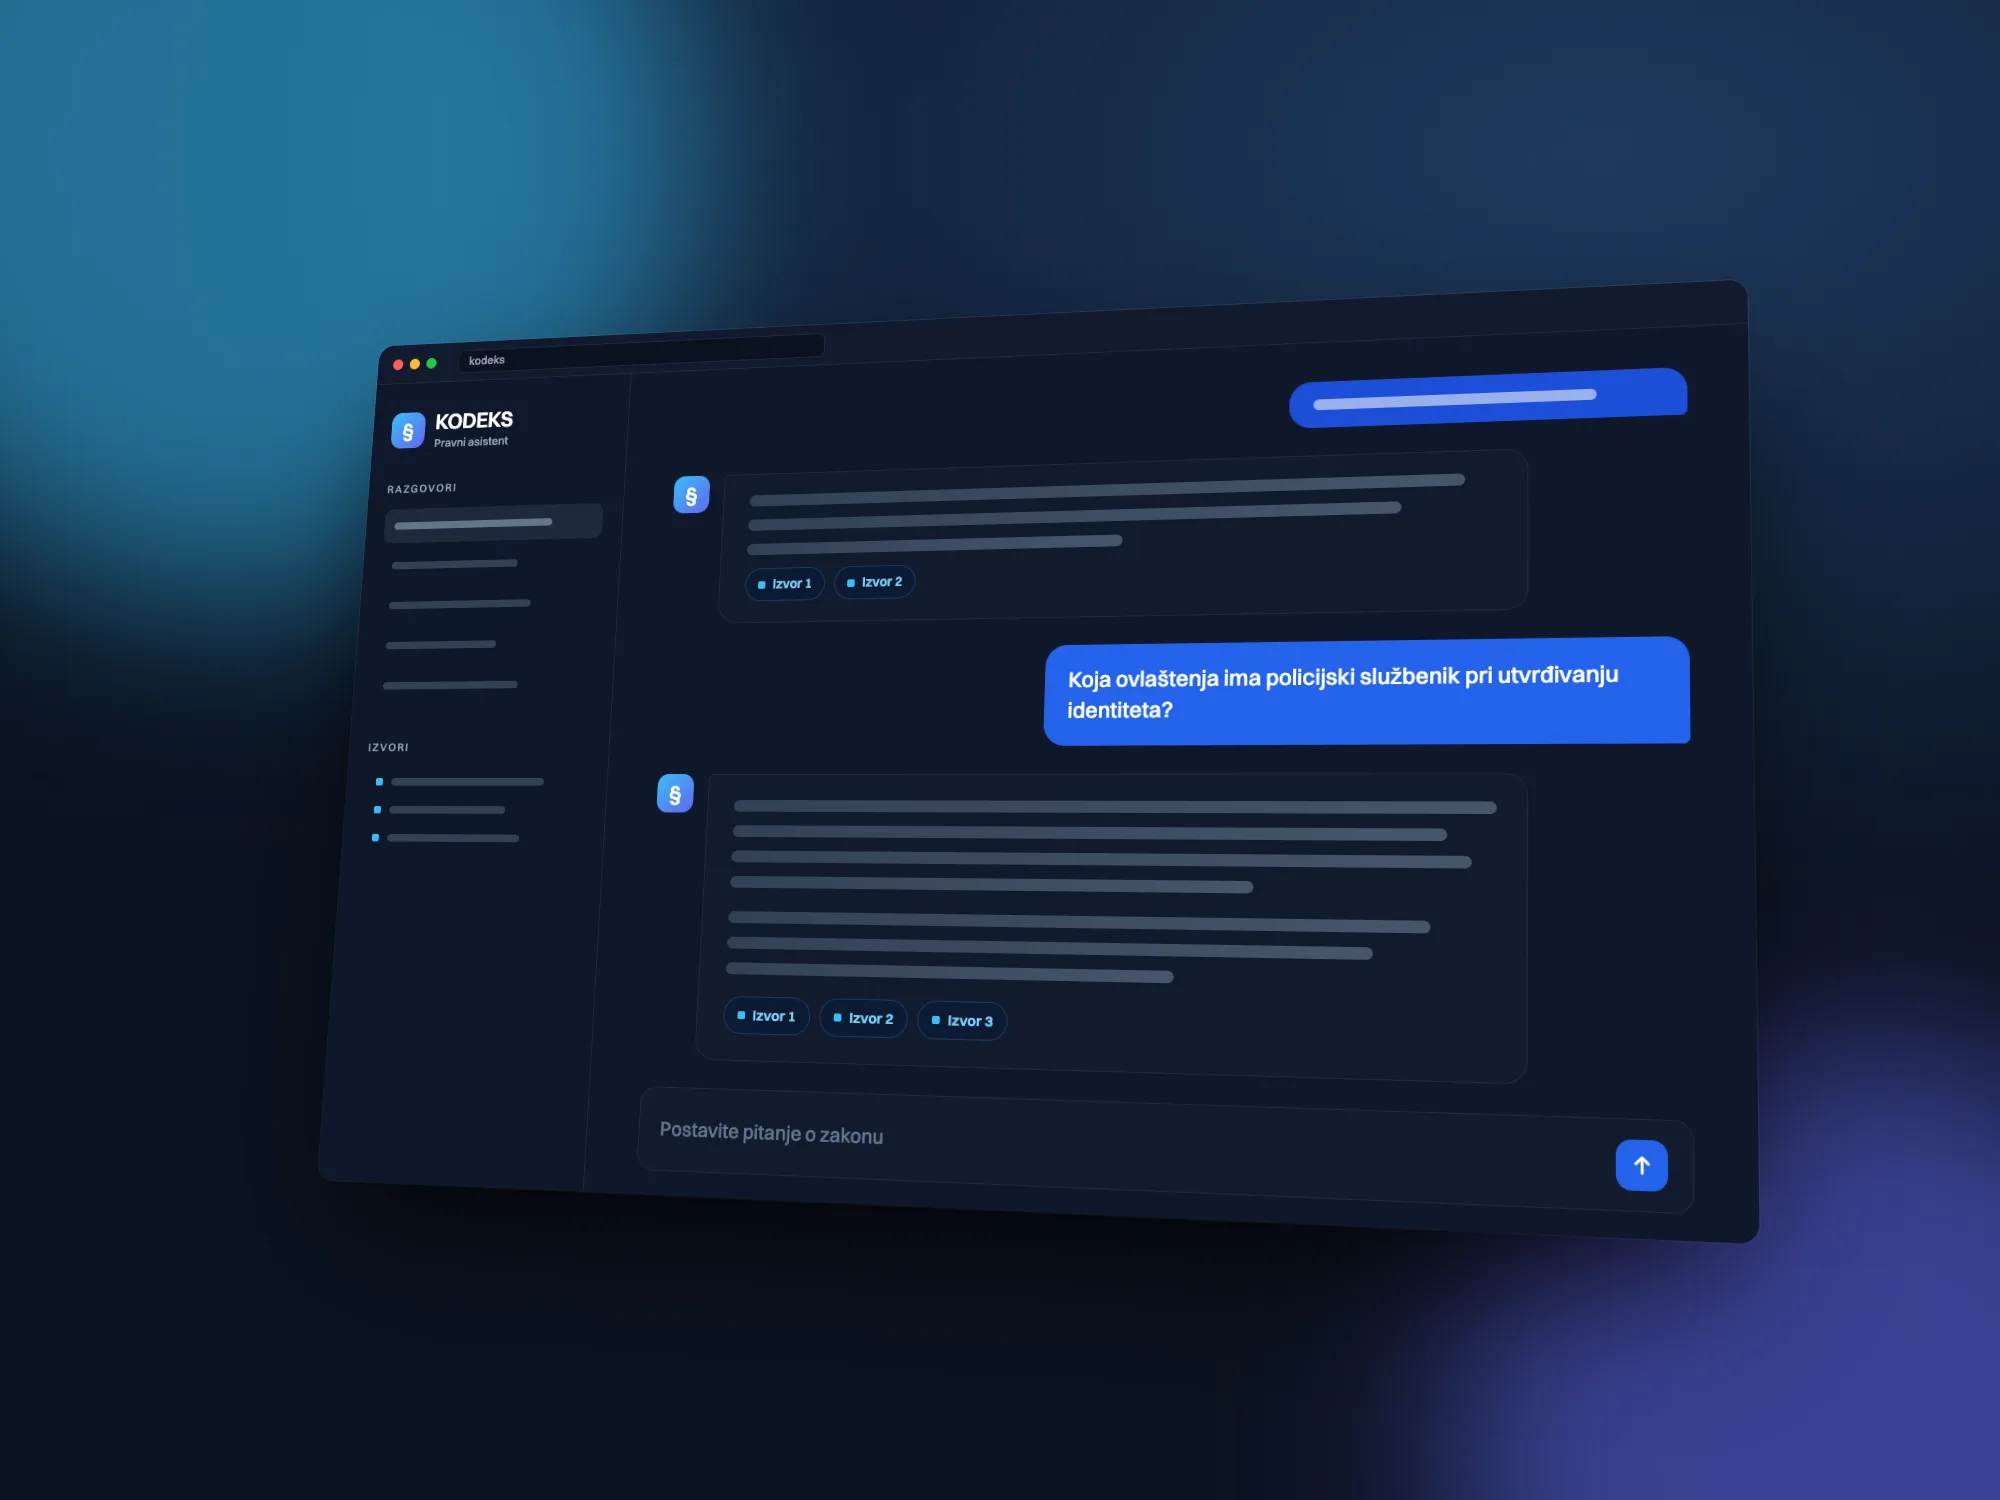
KODEKS
Kada policijski službenik može tražiti identifikaciju osobe?
Prema pronađenim odredbama, službenik može tražiti identifikaciju u slučajevima koje zakon izričito navodi. Za svaki slučaj navodim izvor, pa odgovor možete provjeriti u originalnom tekstu.
Design constraints and decisions
| Constraint | Decision |
|---|---|
| A wrong legal answer is worse than no answer | Answers are generated only from retrieved passages, and every claim cites its source |
| Legal text is long and structured (laws, articles, paragraphs) | Documents are split into passages before indexing, and each passage keeps metadata about where it comes from |
| Users write in Bosnian, Croatian or Serbian | Multilingual embedding model, so meaning matches across language variants |
| Officers need to verify quickly | Citations are shown as clickable sources next to the answer |
| Cost must stay low for a public-sector tool | Small, efficient embedding model; only relevant passages are sent to the LLM |
Architecture
KODEKS has two pipelines. Ingestion runs offline and turns legislation into searchable passages. The query pipeline runs for every question and builds the answer from those passages only.
Legal documents
National legislation
Parse and normalise
Clean, consistent text
Chunk into passages
With metadata: law, article
Embed
text-embedding-3-small
Store vectors
Supabase pgvector
User question
In Bosnian, Croatian or Serbian
Embed question
Same embedding model
Similarity search
Vector search in pgvector
Threshold filter
Keep relevant passages only
Build context
Passages with source IDs
Claude
Grounded system prompt
Answer with citations
Every claim has a source
Threshold filter →No passage passes: fall back. Say what is missing and suggest how to rephrase.
- 1User → Next.js appAsks a question
- 2Next.js app → Embedding APIEmbed the question
- 3Embedding API → Next.js appQuestion vector
- 4Next.js app → Supabase (pgvector)Similarity search
- 5Supabase (pgvector) → Next.js appMatching passages with sources
- 6Next.js app → Claude APIGrounded prompt + passages
- 7Claude API → Next.js appAnswer with citations
- 8Next.js app → UserAnswer and clickable sources
Retrieval, explained
An embedding model turns a piece of text into a long list of numbers, a vector, so that texts with similar meaning end up close to each other. A question about "identifying a person" and an article about "establishing identity" land near each other even though they share few words. That is also why the same question works whether it is written in Bosnian, Croatian or Serbian.
When an officer asks a question, KODEKS turns it into a vector and asks the database for the passages closest to it. Only passages that are close enough, inside the similarity threshold, are passed on to the language model. Everything else is ignored, which keeps the answer focused and the cost low.
Incident: the assistant that returned nothing
During testing, some perfectly reasonable questions came back with an empty answer. No error, no crash, just nothing useful. This is how I found out why.
| Symptom | Some legitimate questions returned an empty answer, while others about the same law worked. |
|---|---|
| Hypothesis | The model was not the problem. Something before it was removing the context it needed. |
| What I checked | Which passages the similarity search returned for the failing questions, before and after the threshold filter, and what the model received when nothing passed. |
| Root cause 1 | The similarity threshold filtered out every candidate passage for questions phrased differently from the legal text. |
| Root cause 2 | The system prompt had no instruction for the "no relevant context" case, so the model had nothing to say. |
| Fix | Tuned the threshold against real questions, made sure the best matching passages are still considered when none clear the bar, and added an explicit instruction: say what is missing instead of guessing. |
Before
Question phrased in everyday words
Empty answer
After
The same question
Answer with sources or an honest "not found in the indexed laws"
"Retrieval and generation fail differently. I now evaluate them separately."
Grounding rules in the system prompt
The system prompt turns the model from a general assistant into a careful one. It enforces these behaviours:
- Answer only from the provided passages.
- Cite the source of every statement.
- Answer in the user's language.
- Say clearly when the passages do not cover the question.
- Never present the answer as legal advice.
Evaluation
I evaluate KODEKS with a set of real questions, each paired with the passages that should be retrieved for it. Retrieval is measured separately from answer quality, so when something goes wrong I know which half of the system to look at.
| Metric | What it tells me |
|---|---|
| Recall@k | Did the right passage appear among the top k retrieved passages? |
| MRR (mean reciprocal rank) | How high the first correct passage ranks, on average. |
| Groundedness | Is every claim in the answer supported by a cited passage? |
| Correct refusal | Does the assistant say "not found" when the law does not cover the question? |
Responsible AI
- Every answer carries citations, so the officer can check the original text.
- No answer is generated without retrieved context.
- An explicit "not legal advice" notice in the interface is planned before wider use.
Next steps, not done yet
Roadmap
Hybrid search
Combine keyword and vector search, so exact legal terms and article numbers match as well as meaning does.
Reranking
Reorder the retrieved passages with a dedicated model before they reach the LLM.
Automated evaluation in CI
Run the evaluation set on every change, so retrieval quality cannot silently regress.
Tracing and observability
Record every query, the passages it retrieved and the answer, to debug and improve with real data.
Stack
| Layer | Technology | Why |
|---|---|---|
| Frontend | Next.js | One framework for the interface and the server-side calls to the AI services |
| Embeddings | OpenAI text-embedding-3-small | Handles Bosnian, Croatian and Serbian well at a low cost |
| Vector store | Supabase PostgreSQL + pgvector | Vectors live next to the rest of the data, in a database I already trust |
| LLM | Anthropic Claude API | Follows grounding instructions closely and writes clear answers with citations |
| Language | TypeScript | One typed language across the whole application |
Glossary
Ten terms, in plain language
- RAG
- Retrieval-augmented generation: the model first looks up relevant text, then answers using only that text.
- Embedding
- A list of numbers that represents the meaning of a piece of text.
- Vector
- The list of numbers itself; texts with similar meaning have vectors that are close together.
- Cosine similarity
- A way to measure how close two vectors are, by the angle between them.
- Chunk
- A passage of a larger document, small enough to search and to give to the model.
- Top-k
- The k most similar passages returned by a search.
- Similarity threshold
- The minimum similarity a passage needs before it is used.
- Grounding
- Making the model answer from given sources instead of its general knowledge.
- Hallucination
- A confident answer that is not supported by the sources or by reality.
- Recall@k
- The share of questions where the right passage is among the top k results.